Sunday, April 29, 2012

Shell Scripting - First Day !!

Aftar long duration, writing this blog on Shell Scripting.. somethinug which is still a new thing for me being in IT industry for more than 5 yeras now. To begin with we will execute HelloWorld program as per the tradition; but before that below is the link which I am using for practicing

http://www.freeos.com/guides/lsst/ch03sec01.html

I have installed cygwin for practicing shell and unix commands, though vi do not work here, you can always type your commands on windows machine [notepad, wordpad or notepad++] and execte those with cygwin. Yes, you can access windows files from cygwin.

First Program - HelloWorld

------------------
#!/bin/sh
#
#First Script of Hello World
echo "Hello World"
------------------
Just run above command on command prompt as below
./HelloWorld.sh


Second Program - Print Contents Inside Files

-----------------------
#!/bin/sh
#
#Second Program to print the content of file
if cat $1
then
echo -e "\n\nFile $1, found and successfully echoed"
fi


Wrote above script in notepad++ ; but when tried to execute that from command prompt, it failed giving below error
./Second.sh: line 9: syntax error: unexpected end of file

But, when I wrote same command from command line itself, it got executed successfully.. Need to know the reason behind this.

Detailed explanation
if cat command finds foo file and if its successfully shown on screen, it means our cat command is successful and its exist status is 0 (indicates success), So our if condition is also true and hence statement echo -e "\n\nFile $1, found and successfully echoed" is proceed by shell. Now if cat command is not successful then it returns non-zero value (indicates some sort of failure) and this statement echo -e "\n\nFile $1, found and successfully echoed" is skipped by our shell.


Now here you will also require a echo parameter description which are as follows

echo [options] [string, variables...]
Displays text or variables value on screen.
Options
-n Do not output the trailing new line.
-e Enable interpretation of the following backslash escaped characters in the strings:
\a alert (bell)
\b backspace
\c suppress trailing new line
\n new line
\r carriage return
\t horizontal tab
\\ backslash

For e.g. $ echo -e "An apple a day keeps away \a\t\tdoctor\n"

Saturday, March 3, 2012

Creating dummy data !!

Just going through oracle blogs, and got focus on below site...http://www.oracle-developer.net/display.php?id=515

Most of the times when you are practicing Oracle or Informatica code, you require a dummy data to be available at table. Particularly when you are working on Performance testing of oracle and informatica, large data is required. How will you create it ? One way is insert some records, then take union of it and again union of it. and so on.. But this will create repetation of data in your table..

Best way is below


Create table test as
SELECT ROWNUM                     AS id
       ,      MOD(ROWNUM,2000)           AS grp
       ,      DBMS_RANDOM.STRING('u',5)  AS val
       ,      DBMS_RANDOM.STRING('u',30) AS pad
       FROM   dual
       CONNECT BY ROWNUM <= 1000000;


Friday, February 17, 2012

Saving an error while DML statement...

It was an interview times, as our project went to tcs... every one was either facing some interview or preparing for the same.

Birwatkar was facing interview at CnC, and below was one of the question asked to him..

How to log errors while performing DML Operations through sql ?


1. First create source and target table
create table insertTestSourec
(
    id varchar(200)   
)


create table insertTestTarget
(id number
)

2. Create error log table using proc create_error_log
BEGIN
  DBMS_ERRLOG.create_error_log (dml_table_name => 'insertTestTarget');
END;

insert into insertTestSourec values(1)
insert into insertTestSourec values(2)
insert into insertTestSourec values('t')


insert into insertTestTarget
select * from insertTestSourec

Here, statement will get rollback and not a single record will get inserted into target table.

Check your error log table using below sql

select *
from all_tables
where table_name like upper('%insertTestTarget%')

3. Verify the error log table
insert into insertTestTarget
select * from insertTestSourec
LOG ERRORS INTO ERR$_INSERTTESTTARGET ('INSERT') REJECT LIMIT UNLIMITED;

4. Here, after execution of above statement, 2 records (1 and 2) will get inserted into target table and incorrect record will get inserted into ERR$_INSERTTESTTARGET.

select *
from ERR$_INSERTTESTTARGET

Thursday, January 5, 2012

Comparing Map and Folders
Ignore In Comparison at Lookup and tranferring that to other folder while migration
With clause query of date range for previous weeks monday - friday

Monday, December 5, 2011

XML Part - II

This is extension to link http://gogates.blogspot.com/2011/09/xml-source.html

We will first see the difference between the options we get while importing the XML definition.

Our XML source is like below taken from link -- http://www.w3schools.com/xml/xml_attributes.asp

<note>
  <date>
    <day>10</day>
    <month>01</month>
    <year>2008</year>
  </date>
  <to>Tove</to>
  <from>Jani</from>
  <heading>Reminder</heading>
  <body>Don't forget me this weekend!</body>
</note>

We used 2 options as seen in the screenshot

This is a first option as

This is a second option as

Basically it changes the xml source node column name. Please find the below difference of both cases


If you see, there is a difference in primary key name and main node name. Second has same name as of xml definition whereas first has name generated of its own.

Friday, December 2, 2011

Map and Session Relation

The relation between a Mapping and a Session is like a relationship between a groom and bride of a hindu family. As in Hindu family, unless you gave divorse to your privious wife or husband, you can not do another merriage, just like that unless you delete a map, you can not assign new map to particular session :) Yes re-namming the map will not do ;-)

We create a map say Map1 and create a session say Session1 and we assign Map1 to Session1 while creating it.


Scenario which I had faced.
Now, I have to do some new development at Map1, but before doing it, I took a copy of it say Map2 in same folder. I completed my development at Map1, but at the end of it, client said ealier thing was fine and he wants that only.

Now, I have Map2 as my original map and Map1 which I have edited. As I did number of changes, I thought its better to use Map2 instead of Map1. So, I renamed Map1 to Map1_Edited and Map2 to Map1.

I ran the session Session1 and surprizingly it got failed.  I checked for the root cause, and when I saw it was running Map1_Edited instead of Map1.

This means, session will stick to its firstly bonded map eventhough you change its name.

How to tackle this?
Now the option I had is to do changes in Map1_Edited itself, but changes were so big that it was a difficult task. I planed that, I will rename Map1 to Map1_Old and re-import Map1_Edited as Map1. So, I renamed Map1  to Map1_Old and exported both Map1_Old and Map1_Edited.

Now my correct map was Map1_Old which I renamed (I renamed the xml of it) and tried to  import it. But at the time of import, it showed me its old name as Map1_Old

Why ?
Thing is, when you rename the map xml, it did not actually renames its Map name but only the xml name.
How?
To rename its actual name, edit the xml and search for

Saturday, November 26, 2011

Basic Materialized View !!

Because of some reason, yesterday was re-creating / arranging my resume again. I was amazed when I came across certification section. Between Jan 2007 to Sep 2009 , in 2 years I had given SCJP, Oracle SQL, SCWCD, ITIL, , Oracle Pl-SQL, Oracle Fundamental-1, and lastly Oracle Fundamental - II, and the thing by which I amazed is, in year 2010 and 2011 I have not done any. :-( Reason was simple, I became satisfied, which kept me apart from learning and achieving more.

Today, went at Zensar Circle again. Met Sir (Ashish Jaiswal) and Sikku Bhai (Sikandar Shaikh), sir explained some things related to Partition Table and as always Sikku Bhai told, its 10 months over now, looking for job change..:) With sir's 30min lecture on Partition table and backup, I got motivated and thought about old days. Around 1, 1.5 years back, had tried number of things on Materialized view, and thought will do something on that before I go to bed...

taking the stuff from below link of "data warehousing guide 10g"-- give this words as search at google.

http://docs.oracle.com/cd/B19306_01/server.102/b14223.pdf

The basic difference I saw in data modeling of Oracle and Teradata is, Oracle advice to create Start Or SnowFlex schema structure and Teradata prefers 3NF. We do not have to bother about advances and dis-advances, both gives us job and money, so both are good.

Oracle uses Bit Map indexes which are mostly created on Fact tables. Below stuff is simply copied from page number 96 [6 - 2] of above link.


"The advantages of using bitmap indexes are greatest for columns in which the ratio of
the number of distinct values to the number of rows in the table is small. We refer to
this ratio as the degree of cardinality. A gender column, which has only two distinct
values (male and female), is optimal for a bitmap index. However, data warehouse
administrators also build bitmap indexes on columns with higher cardinalities.
For example, on a table with one million rows, a column with 10,000 distinct values is
a candidate for a bitmap index. A bitmap index on this column can outperform a
B-tree index, particularly when this column is often queried in conjunction with other
indexed columns. In fact, in a typical data warehouse environments, a bitmap index
can be considered for any non-unique column.
B-tree indexes are most effective for high-cardinality data: that is, for data with many
possible values, such as customer_name or phone_number. In a data warehouse,
B-tree indexes should be used only for unique columns or other columns with very
high cardinalities (that is, columns that are almost unique). The majority of indexes in
a data warehouse should be bitmap indexes.
In ad hoc queries and similar situations, bitmap indexes can dramatically improve
query performance. AND and OR conditions in the WHERE clause of a query can be
resolved quickly by performing the corresponding Boolean operations directly on the
bitmaps before converting the resulting bitmap to rowids. If the resulting number of
rows is small, the query can be answered quickly without resorting to a full table scan." I do not know, why in my old project not a single index was bit-map, thought the structure was Snow Flex..

Lets start with Materialized View now....
What is Materialized View and Normal View ?
Materiazlied view is just like normal view, only thing is it eats its own space at DB which normal view do not. Materialized view keeps its data at its own space wherein normal view always fetches the data from its base tables. Because of Query-Re-write, thought you fire select query on base tables, oracle will fetch the data from materialized view[ If its defined on base tables] and many more...we are not preparing for interview here, so its not important to find out anything more. If needed, go through Basic MV chapter from this book.

Creating materialized view using DB Link, i.e. base tables are in another db, and your MV is in different one -- I had tried it earlier and it was worked that time.. While reading this book came across the line
"If a materialized view is to be used by query rewrite, it must be stored in the same database as the detail tables on which it relies".. this means you can create it, but query re-write will not work, Will try this at end as I do not have another db created at home. Seems Query Re-Write will not work if we are using db link at select query of materialized view, need to check.

Note:- Only thing by which you can not define MV is
"You cannot, however, define a materialized view with a subquery in the
SELECT list of the defining query. You can, however, include subqueries elsewhere in
the defining query, such as in the WHERE clause."

e.g. Query should not be like


select id, name, (select address from myTable), age
from employee

This will not work... All tables has to be at where clause or from clause.


As per book there are 3 types of MVs

■ Materialized Views with Aggregates
■ Materialized Views Containing Only Joins
■ Nested Materialized Views

Some thing imp to read before we start creating MV --
If you specify REFRESH FAST, Oracle performs further verification of the query
definition to ensure that fast refresh can be performed if any of the detail tables
change. These additional checks are:
■ A materialized view log must be present for each detail table unless the table
supports PCT. Also, when a materialized view log is required, the ROWID column
must be present in each materialized view log.
■ The rowids of all the detail tables must appear in the SELECT list of the
materialized view query definition.
If some of these restrictions are not met, you can create the materialized view as
REFRESH FORCE to take advantage of fast refresh when it is possible. If one of the
tables did not meet all of the criteria, but the other tables did, the materialized view
would still be fast refreshable with respect to the other tables for which all the criteria
are met.

Materialized Join Views FROM Clause Considerations
If the materialized view contains only joins, the ROWID columns for each table (and
each instance of a table that occurs multiple times in the FROM list) must be present in
the SELECT list of the materialized view.
If the materialized view has remote tables in the FROM clause, all tables in the FROM
clause must be located on that same site. Further, ON COMMIT refresh is not supported
for materialized view with remote tables. Materialized view logs must be present on
the remote site for each detail table of the materialized view and ROWID columns must
be present in the SELECT list of the materialized view, as shown in the following
example.

CREATE MATERIALIZED VIEW LOG ON sales WITH ROWID;
CREATE MATERIALIZED VIEW LOG ON times WITH ROWID;
CREATE MATERIALIZED VIEW LOG ON customers WITH ROWID;
CREATE MATERIALIZED VIEW detail_sales_mv
PARALLEL BUILD IMMEDIATE
REFRESH FAST AS
SELECT s.rowid "sales_rid", t.rowid "times_rid", c.rowid "customers_rid",
c.cust_id, c.cust_last_name, s.amount_sold, s.quantity_sold, s.time_id
FROM sales s, times t, customers c
WHERE s.cust_id = c.cust_id(+) AND s.time_id = t.time_id(+);

Alternatively, if the previous example did not include the columns times_rid and
customers_rid, and if the refresh method was REFRESH FORCE, then this
materialized view would be fast refreshable only if the sales table was updated but not
if the tables times or customers were updated.

CREATE MATERIALIZED VIEW detail_sales_mv
PARALLEL
BUILD IMMEDIATE
REFRESH FORCE AS
SELECT s.rowid "sales_rid", c.cust_id, c.cust_last_name, s.amount_sold,
s.quantity_sold, s.time_id
FROM sales s, times t, customers c
WHERE s.cust_id = c.cust_id(+) AND s.time_id = t.time_id(+);


You can create a nested materialized view on materialized views, but all parent and
base materialized views must contain joins or aggregates. If the defining queries for a
materialized view do not contain joins or aggregates, it cannot be nested. All the
underlying objects (materialized views or tables) on which the materialized view is
defined must have a materialized view log. All the underlying objects are treated as if
they were tables. In addition, you can use all the existing options for materialized
views.
Using the tables and their columns from the sh sample schema, the following
materialized views illustrate how nested materialized views can be created.
CREATE MATERIALIZED VIEW LOG ON sales WITH ROWID;
CREATE MATERIALIZED VIEW LOG ON customers WITH ROWID;
CREATE MATERIALIZED VIEW LOG ON times WITH ROWID;

/*create materialized view join_sales_cust_time as fast refreshable at
COMMIT time */
CREATE MATERIALIZED VIEW join_sales_cust_time
REFRESH FAST ON COMMIT AS
SELECT c.cust_id, c.cust_last_name, s.amount_sold, t.time_id,
t.day_number_in_week, s.rowid srid, t.rowid trid, c.rowid crid
FROM sales s, customers c, times t
WHERE s.time_id = t.time_id AND s.cust_id = c.cust_id;

To create a nested materialized view on the table join_sales_cust_time, you
would have to create a materialized view log on the table. Because this will be a
single-table aggregate materialized view on join_sales_cust_time, you need to
log all the necessary columns and use the INCLUDING NEW VALUES clause.
/* create materialized view log on join_sales_cust_time */
CREATE MATERIALIZED VIEW LOG ON join_sales_cust_time
WITH ROWID (cust_last_name, day_number_in_week, amount_sold)
INCLUDING NEW VALUES;
/* create the single-table aggregate materialized view sum_sales_cust_time
on join_sales_cust_time as fast refreshable at COMMIT time */
CREATE MATERIALIZED VIEW sum_sales_cust_time
REFRESH FAST ON COMMIT AS
SELECT COUNT(*) cnt_all, SUM(amount_sold) sum_sales, COUNT(amount_sold)
cnt_sales, cust_last_name, day_number_in_week
FROM join_sales_cust_time
GROUP BY cust_last_name, day_number_in_week;

Nesting Materialized Views with Joins and Aggregates
Some types of nested materialized views cannot be fast refreshed. Use EXPLAIN_
MVIEW to identify those types of materialized views. You can refresh a tree of nested
materialized views in the appropriate dependency order by specifying the nested =
TRUE parameter with the DBMS_MVIEW.REFRESH parameter. For example, if you call
DBMS_MVIEW.REFRESH ('SUM_SALES_CUST_TIME', nested => TRUE), the
REFRESH procedure will first refresh the join_sales_cust_time materialized
view, and then refresh the sum_sales_cust_time materialized view.


================ First MV =======================

CREATE MATERIALIZED VIEW cust_sales_mv
PCTFREE 0 TABLESPACE demo
STORAGE (INITIAL 16k NEXT 16k PCTINCREASE 0)
PARALLEL
BUILD IMMEDIATE
REFRESH COMPLETE
ENABLE QUERY REWRITE AS
select sum(salary),count(emp.department_id), department_name
from hr.employees emp, hr.departments dep
where emp.department_id = dep.department_id
group by department_name

I fired above query, on hr schema and got an error
"insufficient privileges"

So, logged in as SYS, fired again and got an error
"table space demo does not exists"

What table space do sys user/schema has ?
Checked it at
select *
from DBA_TABLESPACES

or
  • USER_TABLESPACES
  • V$TABLESPACE
and found number of, so used "USERS" and modified the query


CREATE MATERIALIZED VIEW cust_sales_mv
PCTFREE 0 TABLESPACE users--demo
STORAGE (INITIAL 16k NEXT 16k PCTINCREASE 0)
PARALLEL
BUILD IMMEDIATE
REFRESH COMPLETE
ENABLE QUERY REWRITE AS
select sum(salary),count(emp.department_id), department_name
from hr.employees emp, hr.departments dep
where emp.department_id = dep.department_id
group by department_name

MV got created in 10 sec.

Fired select statement of MV and checked the Explain plan

It seems, Query re-wite worked and now data is getting fetched from MV and not from Base Tables.

Tuesday, November 22, 2011

connect by level !!

Every day teaches you something new,,, only thing is, you should keep your eyes open and ears alert.

While working on INC today, got something new like below - which I had never thought of.

select to_date(startDate,'dd-mon-yyyy') - 1 + level
from dual
connect by level <= (to_date(endDate,'dd-mon-yyyy')+1) - to_date(startDate,'dd-mon-yyyy')

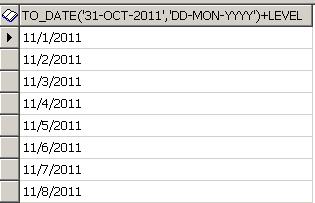
Scenario was, start date and end date are 2 IN parameters for my proc. Using those, they were generating date ranges. Lets say, you gave start date as 1-Nov-2011 and end date as 10-Nov-2011, So the query will generate 10 rows with 1st to 10 Nov as data.
As in image, query will generate the result.

How will it work?
Seems, there is a keyword connect by level just as connect by prior.

select  level
from    dual
connect by level <= 10 ;
 
When you fire above statement, it will 
generate records with 1 to 10 numbers.
 
Same logic they have used in generating Date Range series. Level they have creating 
by subtracting End Date and Start Date and simply added level to start date. As 
keeps on increase at every iteration, date gets increase along with it.
  
You can get more information at google, but following like I like most
http://www.sqlsnippets.com/en/topic-11821.html  

They query you can use for date series preparation is
select to_date('1-Nov-2011','dd-mon-yyyy') -1 + level 
from dual
connect by level <= (to_date('9-Nov-2011','dd-mon-yyyy')+1) - to_date('1-Nov-2011','dd-mon-yyyy')

Sunday, November 13, 2011

How do they do it - Part - 1

It may be very trivial or unimportant thing to most, but for me, it was a dream come true. I observed most of the people who do not work on HTML / UI Development, are really not interested in how do they create this UI, but not sure how, I am very fond of it.

After hearing much about jQuery and CSS, and observing www.bbc.com and www.google.org, I was wondering, how they have developed this site.
Just simply open these sites from FireFox browser - if you open those from IE you can see the html code but won't able to see the css behind those.

To start with, we will first see the www.bbc.com, which is full of css3 and jQuery. Image Rotation, Panels and number of things are with jQuery and definetly of css.

Here, we see how the right pan of bbc.com is made of...that is, when you scroll your mouse, numbering gets lighten.

Below is the basic code without applying css and it looks like below --

<html>   
    <div id="mostPopular_tabset_watched" class="selected panel">

           
        <ul class="blq-clearfix">
   
               
                <li class="ol0 first-child">
                    <a rev="mostpopular|homepage|na|r|t|i|text|content" href="http://www.bbc.co.uk/news/world-us-canada-15319106"><span class="livestats-icon livestats-1">1: </span>Mandar</a>                </li>

               
                <li class="ol1">
                    <a rev="mostpopular|homepage|na|r|t|i|text|content" href="http://www.bbc.co.uk/2/hi/8148527.stm"><span class="livestats-icon livestats-2">2: </span>Korea plane lands on its tail</a>                </li>

               
                <li class="ol2">
                    <a rev="mostpopular|homepage|na|r|t|i|text|content" href="http://www.bbc.co.uk/2/hi/asia-pacific/7874393.stm"><span class="livestats-icon livestats-3">3: </span>Australian pilot does a &#039;Hudson&#039;</a>                </li>

               
                <li class="ol3">
                    <a rev="mostpopular|homepage|na|r|t|i|text|content" href="http://www.bbc.co.uk/2/hi/programmes/click_online/9615908.stm"><span class="livestats-icon livestats-4">4: </span>Ceatec - pushing a touch screen&#039;s buttons</a>                </li>

               
                <li class="ol4">
                    <a rev="mostpopular|homepage|na|r|t|i|text|content" href="http://www.bbc.co.uk/news/video_and_audio/"><span class="livestats-icon livestats-5">5: </span>One-minute World News</a>                </li>

   
        </ul>

   
    </div>
</html> 


Wednesday, October 26, 2011

Viewing Old Map Version at Informatica....

If you are relying on Infomatica's versioning functionality - dependance is poor death. Had a very bad experience .. please read below...


Not sure, what was the day, most of the ppl were not in office. Got a new QC and RK assigned that to me. To start with exported the workflow and before importing to ravi's folder, just confirmed with him if someone else is using or not. After his Yes, imported workflow, and started working on new qc.


Process is, we have write access to user and poroject fodler but not for qa and prod. We need to export workflows from qa and import those to user folder. Have to complete development and testing at User folder and after UAT sign-off, we migrate code to project folder. From Project -->> QA -->> Prod pada will take care the migration process. PADA is a tool for migration.


Till 5, completed the 10% of work, went for the tea, came up by 5:30; that time got a ping from Sergey that when he tries to do testing for scenario, mapping is getting failed. Thought, my qc is not so urgent, so will help sergey to resolve the issue.


Went to feed, and checked from which folder his is running the mapping and felt like standing alone in desert, no water, and close to dye. :-(


Yes, I had imported my new code, where Mansi had did his development. I had replaced my all overlapping targets, sources, maps, tranformations in ravi's folder where mansi's code was there for UAT. All got messed now, and map got invalidated and because of which Sergey could not test the things.


Informed him that we have some issues at informatica level and trying to resolve those. As this situation was quite new to me, I asked help to dada (abhishek sengupta).


Below are the things we tried...


1. Checked for the versions, that what all objects got affected. But it was very hard to find it out, as numberof maps and source/targets were involved.
2. So, decided to go one by one with maps, which are affected. Took first map, checked the version..from the comment which I gave while importing, I could easy find out the affect maps.
3. To get the old version, I right click on respective version and click on Open In Workspace, and that particular map version got opened.
4. For first time, I felt my ass got saved, and I can re-commit this version, but when I checked the targets, it was still showing as latest version, it was not same as the map version.
5. I checked if really old target version is present at informatica, and went to targets and checked the versioning, yes that version was present,
6. I checked the dependancies for old target, it showed me map of that version.
7. I opened that map in workspace again, but no luck, again target was of latest version :-(..


This is a dam bug in informatica, that it shows everything of old version except the targets and because of which though you could see rest old part, its of no use.


Below is a replica of such scenario...
1. I am reducing the target table ports in my project folder map; keep in mind - only when your ports gets reduced, it will really affect the map as original ports will get dis-connected. When you add new ports, it will not affect the map.
2. Refresh the affected map, where this target got used.
3. Export the map and import it at QA folder. Replace all objects, so now QA will have also one target for which one port got deleted.
4. Check in all objects which you have newly imported to QA folder.
5. Now, right click on map and click on versioning --> View History
When you click on view history, new window will appar which will display you the total number versions exists till now.
6. Just again right click on object (here its map) of version you want, and click on Open In Workspace.


Here, all things work fine - means you will be able to view all objects in a map which belogs to that old verison, except target definition. This is a bug of informatica, that it wont show Target of that particular version but the target is always of latest version.

So, suppose you in-intentionally or un-knowingly copied your map or done some changes in map of a particular folder, and if the older version of that map got updated. Then you can view/get your old map iff the target defination is not changed.

If you have done some changes at target definition like added more columns, connected more ports to target level etc.. then there is no way to get your old version back, and you need to do your development again for earlier version.

All about CSS

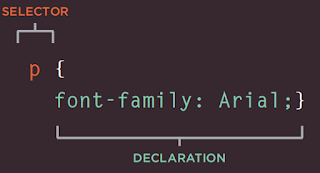
From book HTML & CSS - Design and Build Websites - Jon Duckett CSS works by associating rules with HTML elements. These rules govern how...